GPU clusters for AI training

Coordinate the hardware and software needed for larger AI training workloads. Curobotic’s GPU cluster solutions connect compute nodes, data access and workload management around the models, experiments and users the system must support.

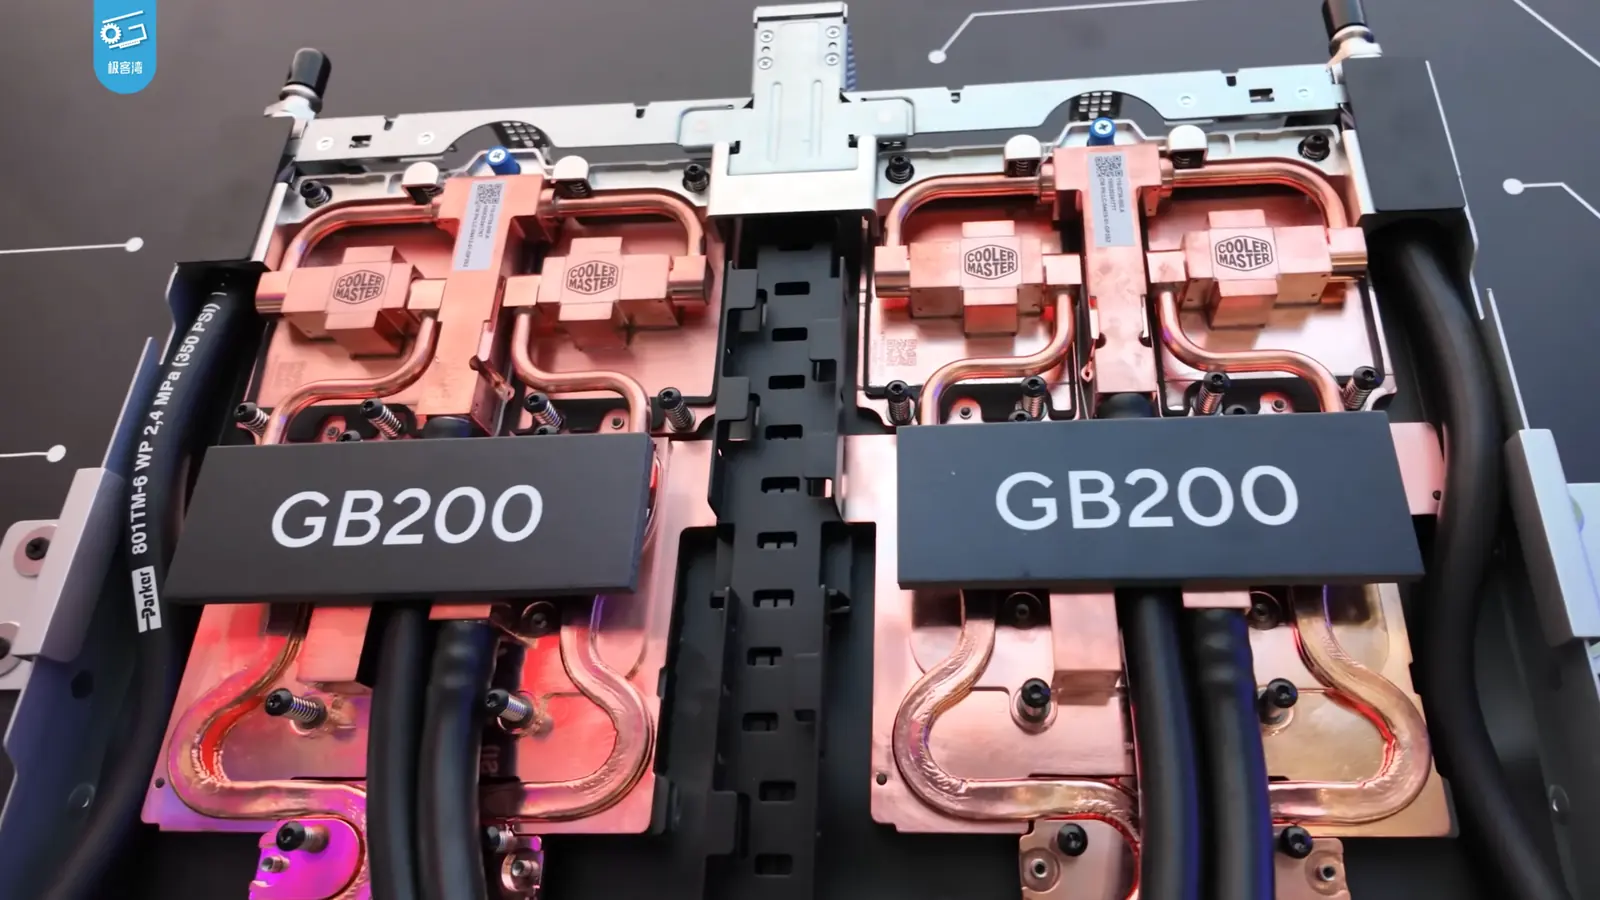
A pair of NVIDIA GB200 compute assemblies with liquid-cooling blocks and connected pipes
NVIDIA GB200 compute tray Photo credit

How the solution fits together

Built around your users.

Workload sizing

Establish memory needs, concurrency and whether training spans several nodes.

Inside the solution

The complete working environment.

Choose the right scale first

Not every training project benefits from a multi-node system. We examine model memory, training duration, parallelism and expected concurrency before proposing a cluster. A single server may be appropriate for one workload, while a shared pool of nodes may serve several independent teams more effectively than one tightly coupled job.

Compute and communication together

The architecture considers accelerator compatibility, host resources, device connections and communication between nodes. Network and storage choices must match how the training code exchanges data. The proposal records these assumptions and identifies which parts require a representative benchmark before performance expectations can be accepted.

Data pipelines and experiment space

Training data has to be prepared, staged and retained with a clear ownership model. We separate active working datasets from source records and long-term outputs. The scope can include shared storage, local scratch space and documented transfer paths, with permissions that reflect project boundaries and the sensitivity of the underlying data.

A managed training environment

User access, job scheduling, reproducible software environments and monitoring turn nodes into a shared service. The design addresses failed jobs, maintenance windows and how capacity is reserved. Operational handover explains which team manages the infrastructure and which team owns model code, training decisions and evaluation of the resulting models.

Quote-based cluster configuration

The quotation separates nodes, fabric, storage, software, deployment and support. Facilities requirements and paid benchmark access are identified before procurement. Send your model or workload brief, current training method and intended users so we can scope a cluster proposal with explicit assumptions and a practical acceptance test.

Connected services & systems

Complete your project scope.

Does twice the GPU count mean twice the performance?

No. Scaling depends on the model, parallelisation method, data pipeline and communication overhead. A measured comparison under stated conditions is needed. We separate component specifications from claims about the time your actual training run will take.

Can the cluster serve several AI teams?

It can be designed for multiple projects, with allocation rules, access boundaries and accounting appropriate to the organisation. The number of simultaneous workloads depends on their resource requirements. Those policies should be agreed before users begin sharing the system.

Can this project be delivered in Guwahati and other Northeast locations?

Curobotic is based in Guwahati, Assam. We scope projects for organisations in Assam, Itanagar and other parts of Arunachal Pradesh, and Shillong. Remote preparation, site visits, freight and on-site installation are agreed in the quotation according to access, facilities and the work required.

Your next chapter starts here.

Let’s scope your next system.

Share your workload, location and timeline. We will prepare a quotation for the agreed configuration and delivery scope.

admin@curobotic.com